Teaching AI to Explore the Physical World
Making scientific exploration measurable
SDL-2 tests whether AI agents can find a processing route that meets a magnetic performance target for a new NdFeB powder. Frontier agents usually ruled out a route that worked, and training made ours a better explorer.
Our thesis
Our meta-learning thesis is that agents can learn how to investigate unfamiliar physical systems through verified experimental experience. Experience should reduce the experiments needed to establish the next capability, even when the answer itself does not transfer.
We use experimental measurements to refine the digital twin, where agents can test ideas between lab runs. The lab retains evidence and methods across investigations, while outcomes verified in the twin train the agent’s policy. SDL-2 tests whether an agent’s experiments support a correct decision about a material process.
An investigation starts from a material objective, a requirement for a new powder lot. Agents built on any language model can run in parallel. Each reads the evidence, models it with tools such as physics models, optimizers and code, records a forecast before a result and then chooses the next experiment, waits or decides. The same experiment and forecast can go to the digital twin, a simulation built from measured data that runs any of the 2,976 routes on a new lot and returns results within minutes, or to the experimental campaign at Rensselaer Polytechnic Institute, where the lab reviews each proposal, makes and measures the samples and releases measured results over days. Every forecast, result and decision is written to the campaign record. SDL-2 uses the record to check each final decision, and verified outcomes are used to train the agent. The twin is built to be re-anchored on measured results from the experimental campaign.
Process development is where this matters. A material is useful once a process makes it reliably, and every new powder lot, machine, scale or spec reopens the question. When an experiment falls short, the process may be impossible, or the right combination may be untested. Telling those apart takes a whole investigation, so the whole investigation is what we evaluate.
What an investigator has to get right, and where SDL-2 measures it
Identify what to model
Adopt an executable model and test its forecasts
Identify consequential relationships
Which variable decides this lot
Choose useful evidence
Build the decisive combination
Learn from the results
Forecasts recorded before results, then revised
Use the understanding later
The nominated route holds on a new batch
Our earlier benchmarks, VOE-Bench and SDL-1, used real experimental records to test whether an agent can tell when the evidence is enough and how it learns from experiments. SDL-2 lets the agent run any experiment in a declared process space, and the digital twin returns a simulated result for every route it proposes.
How the agent investigates
We asked the language model to work the way a process engineer does, with tools. Agents could run, test and replace executable models, then use them to record forecasts and choose the next experiment. In our experimental campaign, measured densities supported the density models. Magnetic estimates depended on historical evidence and stated assumptions, with current-specimen magnetic measurements still needed to test them. The agent’s job was to decide which explanation the evidence supported and what measurement could change the next action.
The same kind of agent worked in two places. In the digital twin it could run any route in the declared process space, starting from a deliberately imperfect physics model. In the experimental campaign, each proposal waited for the lab, and results arrived in the order they were measured.
What an agent saw in a measured specimen
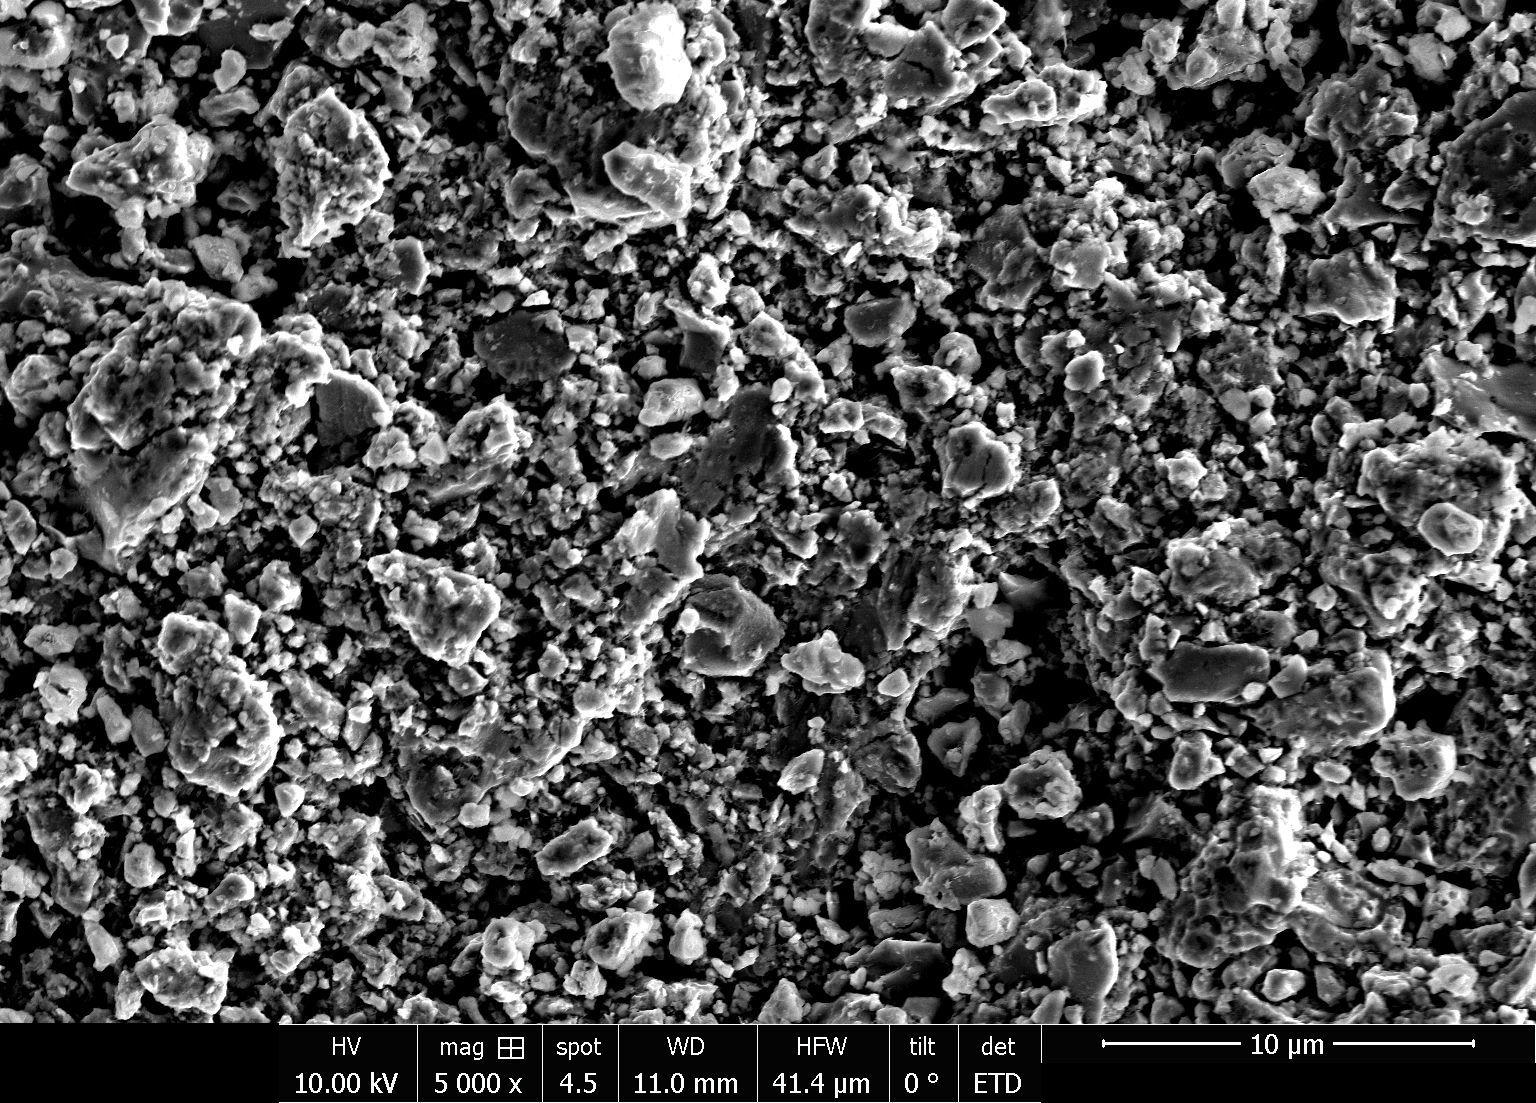
GLM-5.3 Flash · step 113
Looked at this image from the campaign’s experimental data
Step 114
“The SEM of sample #1 at 750 °C: shows loose, angular powder particles of ~2-10 µm barely sintered — very porous, particles retain their powder morphology, minimal necking. This is consistent with 63 %TD and with minimal grain growth. … the tool predicted grain ~3.25 µm mean at 750 °C. The SEM qualitatively supports particles ~1-10 µm (powder was 4 µm nominal).”
Step 116
Compared a second specimen, recorded its findings and decided to wait for the next result
“Both SEMs confirm the same story: porous, powder morphology retained (1–15 µm angular fragments), minimal necking”
Every experiment extends a decision graph. Each step links the agent’s belief, recorded as a forecast before the result whenever it commits one, to the intervention it chose, the evidence that came back, the update it made and the consequence for its next move. Because the forecast comes first, the campaign record shows what the agent expected as well as what it concluded. Scoring reads this record to check whether the evidence supported the final decision, and training finds its decision points in it.
The record persists when the investigator changes. Another agent can inspect the original measurement, rerun the calculation and question the revision. Shared research memory keeps executable methods and failed approaches alongside unresolved disagreements. This gives subsequent investigations something they can test and improve, with the evidence behind it still available.
Does the language model predict material properties?
No. Physics models fit to measured data produce the numbers, and the agent can fit, test and replace them. The agent decides which model to trust, which measurement would change its mind and when the evidence supports a decision. Its forecasts are then scored against what is measured.
Why not run Bayesian optimization?
An optimizer proposes experiments for a stated objective, and the agent can call one as a tool. SDL-2 measures the decisions around it, such as which processing variable matters for this lot, which measurement separates two explanations and when to stop or commit. Those decisions are where frontier agents fail most often. We ran Bayesian optimization and design of experiments with the same powder lots, tools, 570-credit allowance and graders. They reached 7 and 6 correct, justified decisions on the 29 sealed worlds, compared with 8 for Claude Opus 5.5. Most final decisions remained incorrect or unsupported.
Task and scoring
Each SDL-2 world is a neodymium–iron–boron (NdFeB) powder lot with hidden physics. The agent must find a process route whose 3 specimens from one new preparation all reach 10 kOe coercivity and 11 MGOe energy product, or conclude that no route in the declared space can.1
The agent sets degassing, sintering temperature, pressure timing and annealing, and pays for specimens and measurements in credits. Credits are SDL-2’s experiment currency. Each purchase is priced to model its experimental cost, from 1 credit for a density measurement to 50 for a full magnetic curve, and each investigation has 570 credits and up to 12 new specimens. Credits are separate from what the model’s API calls cost.
Each final decision is scored twice, with no LLM judge. Outcome checks that the decision is correct in the simulated world. Justified checks that the agent’s own measurements support the decision, using a Bayesian posterior under a declared evaluator prior that the agent does not see. The headline score, Both, requires both.
Worlds and admission
The panel has 29 sealed worlds, 23 drawn from held-out regions of the generator and 6 in distribution. Every world passed admission checks, including a scripted investigation that reaches a supported decision of the right kind within budget and a cap on prior-only shortcuts. The task and environment page shows the full contract the agent receives.
Frontier results
We ran six frontier models once on each sealed world, all at high reasoning effort. Claude models ran in Claude Code and the others in the Pi agent harness. Claude Opus 5.5 led at 27.6% and Gemini 4 Argon followed at 24.1%. With 29 worlds the intervals overlap, so the ordering is descriptive. A policy that always concludes no route exists scores zero on Both.
Frontier agents reached a correct, justified decision in under a third of investigations

Exact data, experiment spending and cost
| Model | Both | Outcome | Justified | Mean credits | API cost per attempt |
|---|---|---|---|---|---|
| Claude Opus 5.5 Claude Code | 8/29 12.7%–47.2% | 8/29 12.7%–47.2% | 9/29 15.3%–50.8% | 493.9 | Subscription |
| Gemini 4 Argon Pi | 7/29 10.3%–43.5% | 8/29 12.7%–47.2% | 9/29 15.3%–50.8% | 498.2 | $9.17 |
| Claude Sonnet 5.5 Claude Code | 6/29 8.0%–39.7% | 6/29 8.0%–39.7% | 7/29 10.3%–43.5% | 496.3 | Subscription |
| GPT-6 Astra Pi | 4/29 3.9%–31.7% | 4/29 3.9%–31.7% | 6/29 8.0%–39.7% | 501.8 | $10.36 |
| GLM-5.3 Flash Pi | 3/29 2.2%–27.4% | 4/29 3.9%–31.7% | 3/29 2.2%–27.4% | 437.6 | $0.40 |
| DeepSeek V4.1 Flash Pi | 2/29 0.8%–22.8% | 4/29 3.9%–31.7% | 6/29 8.0%–39.7% | 516.9 | $0.20 |
| Ours DeepSeek V4.1 Flash · Pi | 5/29 5.8%–35.8% | 5/29 5.8%–35.8% | 5/29 5.8%–35.8% | 564.7 | Not comparable |
Counts are correct decisions out of 29 worlds, with exact 95% binomial intervals beneath. Credits are SDL-2’s experiment currency, from an allowance of 570. API cost is the mean per counted attempt, from provider billing where recorded and token prices otherwise, excluding attempts rerun after provider errors. Claude models ran on a subscription, so no per-attempt cost applies. Model and harness are paired, so the panel compares complete agent systems. Ours sampled a trained checkpoint on Tinker rather than a provider API, so its cost is not comparable with the rows above.
How investigations end
The clearest pattern is the decision to stop. In worlds where a passing route exists, 108 of 156 attempts concluded that none did, and 19 ended without a decision. Only 18 nominated a passing route.
With an explicit Bayesian stopping rule, Bayesian optimization ruled out 0 of the 26 lots that had a passing route. Bayesian optimization and design of experiments nominated failing routes on 18 and 19 of those 26 lots, respectively. We want agents that can use optimizers while reasoning about which processing choices matter and when the evidence supports a conclusion.
Why did they stop? A magnet has to resist demagnetization, measured as coercivity, and store energy, measured as energy product, and in these worlds the processing conditions that raise one often lower the other. A passing route needs one pressure schedule paired with a matching degassing dose. In every model except GPT-6 Astra, most arguments for ruling a lot out rested on the trade-off measured on the routes the agent had built, extended to every route. Claude Opus 5.5 wrote, “The two limits sit at opposite corners of a trade-off that every measured route follows.” The starting agent in the training example below made the same argument in its own words, “the Br-Hci tradeoff is strict.” The trade-off held on the routes they tried, and not for the pairing they never built.
Two counts show where investigations go wrong. In 105 attempts, the agent never built the decisive combination of degassing dose and pressure schedule, and none of those attempts passed. In 60 attempts, the evaluator, reading the agent’s own evidence, already supported a passing route that the agent did not nominate.
Most investigations of a workable process ended by ruling it out
How far each investigation got
Across all models, 18 attempts nominated a passing route, 11 nominated a failing route and 19 ended without a decision.
Where each model stopped
Claude Opus 5.5 built the decisive combination in 8 of the 26 worlds where a passing route exists and nominated a passing route in all 5 where it measured one. Gemini 4 Argon built it in 9 and nominated a passing route in 5 of the 6 where it measured one. GPT-6 Astra built it most often, in 12, but nominated a passing route in only 3 of 10 and usually ended without a decision.
An analysis after the runs compared the processing choices behind correct, justified decisions. On lots with a passing route, all 15 such decisions by the four highest-scoring frontier models used annealed routes. Bayesian optimization and design of experiments used no anneal in 7 of their 9 such decisions. They tried an average of 0.5 and 1.4 anneal programs per investigation on those lots.
Bayesian optimization and Claude Opus 5.5 shared 2 of the 13 worlds where either reached a correct, justified decision. A fixed design carries its designer’s beliefs about the material. An agent can choose the processing variable for each lot.
Training changes how the agent searches
Our training method works on decision points, the steps where new evidence should change, or justify keeping, the agent’s model and its next experiment. The idea follows PivotOPD and PivotRL, which concentrate training on a few pivotal turns in a long agent run. The decision graph lets us find decision points with a fixed rule instead of a language model judge. Training runs in two stages. Supervised learning trains on the moves the agent made at selected decision points. Reinforcement learning then credits every step of an investigation, not only its decision points, with the verified outcome of the whole investigation.2
We trained DeepSeek V4.1 Flash this way in the digital twin. Supervised learning on its own earlier investigations gave the starting checkpoint, and the results below compare that checkpoint with the policy after reinforcement learning. The run made 12 updates across 32 training lots.3
The trained agent searched more systematically and more narrowly. It more often held the pressure schedule fixed while varying degassing, and more often repeated its chosen route on a new batch before claiming it. It committed more often, ending without a decision in 2 of 64 investigations, down from 16. It probed a rarely decisive pressure onset less often, discovered a passing route less often and wrongly ruled out a working process more often, in 23 investigations against 14. On 16 never-run lots, correct decisions held at 21 of 64.
After training, the agent searched more systematically and more narrowly
Where the new search paid off depended on the world. On development lots where degassing decides, correct decisions rose from 4 to 14 of 48. Where pressure timing decides, they moved from 18 to 13. The agent learned the processing variable that mattered most in its training worlds, together with a more systematic way to test it.
The trained agent learned which processing variable mattered most in its training worlds
Ruling a lot out is the most consequential call in process development, because it ends the search. On the lot below, the starting agent made that call from a confounded comparison, in which pressure schedule and degassing changed together. The trained agent held its best schedule fixed, varied degassing alone and measured full curves on its leading candidates before nominating, which is how a process engineer attributes an effect to one variable. The two agents started from the same evidence and diverged after their first screen. No demonstration showed it the answer. Reward on whole investigations changed which branch the policy took, and that branch produced evidence that separates explanations.
On the same lot, the trained agent tested degassing and found the route
Same lot, same starting evidence
Each agent opened with a broad screen of pressure schedule, peak temperature and degassing, then branched
Starting checkpoint
Added anneal steps to push coercivity
Read a strict trade-off
“the Br-Hci tradeoff is strict”
One last anneal failed to break it
Concluded no route exists, an incorrect decision
A passing route existed
After training
Locked the best schedule, then varied degassing
Revised its model
“Anneal is not needed and not helpful”
Measured full curves on its two leading candidates
Nominated the route it measured, a correct decision
Correct in the simulated world
Every step of both investigations is in the investigation replays, together with the other 13 cases where only one of the two agents was correct.
We then tested three checkpoints from this run on the 29 sealed worlds. The policy after 6 updates explored the most of the three, finding a working process more often than every frontier model except GPT-6 Astra. It reached more correct, justified decisions than GPT-6 Astra and the starting checkpoint, though it still often measured a passing route without nominating it.
What an agent learns to explore follows the worlds it practices in. Here a reward on whole investigations changed exploration first. Denser, physically grounded feedback has moved accuracy in our earlier training release and a physics-verifier study, which is why we widen the training worlds with physical evidence as it comes in.
Training statistics and definitions
In the full agent harness, the trained policy reached 5 correct decisions of 32 against 4 for the starting checkpoint. On the never-run lots, the difference in correct decisions was 0.0 points with a 95% lot-resampling interval of −12.5 to +14.1.
The sealed-world runs of the three checkpoints were pre-registered before any of them started. Correct, justified decisions were 4, 5 and 5 for the starting checkpoint and the policies after 6 and 12 updates, against 2 for DeepSeek V4.1 Flash without our training. The pre-registered difference between the 6-update policy and the starting checkpoint was +3.4 points, with a 95% world-resampling interval of −6.9 to +13.8. On the 26 feasible worlds, the three checkpoints measured a passing route in 5, 8 and 4, against 2, and ruled out a working process in 21, 19 and 21, against 20. They ran controlled degassing comparisons in 9, 10 and 7 investigations, against 3, and replicated their chosen route on a fresh batch in 3, 3 and 0, against 1.
We chose the 6-update checkpoint after reading the 12-update results on the never-run lots, where in the lean interface it had reached more correct decisions, so that advantage was a selected estimate and the sealed worlds test it independently. As predicted before the runs, the 6-update policy matched or beat the 12-update policy in finding passing routes, recovering from a missed first design and reaching correct decisions. The leaderboard lists the best of the three on this panel as Ours, which biases that row upward by about one to two worlds. The checkpoints were trained in the lean interface and ran here in the full harness. They sampled trained weights on Tinker with a 262,144-token context, so every investigation compacted its context, while the frontier DeepSeek V4.1 Flash row ran through the provider API without compaction. Attempts that spent past the allowance failed Outcome, as in the frontier panel, which applied to 1, 4 and 4 attempts. We reran the 9 attempts that ended when the sampler returned a turn the harness could not parse, and those failed attempts are not counted. The comparisons are descriptive at 29 worlds.
Controlled degassing comparisons count investigations that measured at least three degassing conditions with every other condition held fixed, excluding first-design specimens. That threshold and the pressure-onset measure were defined after the results. Recovery after a missed first design fell from 16 of 42 to 7 of 41.
The supervised stage selected the agent’s follow-ups to contradicted forecasts and its correct claims that rested on its own measurements, using a deterministic check on the record with no language model choosing targets. In an earlier round with a different model, only 2 of 82 profiled decision points produced different rewards across samples, which is why the reinforcement learning stage credits whole investigations. Training lots were filtered with the simulator’s ground truth toward lots with many passing routes, and this report covers a single run. Model weights are not released with v1.0.
Our experimental campaign
Our experimental campaign runs with Rensselaer Polytechnic Institute (RPI), where samples are made by spark plasma sintering and measured. In the initial investigations, agents built on five frontier models received experimental records in sequence, recorded forecasts and proposed further experiments. They reasoned with a shared physics model refit on measured densities.
The material objective is a reproducible NdFeB process without dysprosium or terbium that achieves Hci ≥20 kOe and (BH)max 45–48 MGOe together, with operating-temperature verification. SDL-2 uses a lower target of 10 kOe and 11 MGOe, grounded in historical isotropic-magnet measurements, to construct exploration scenarios where different processing combinations determine success. Agents must discover those combinations and gather enough evidence to decide whether a viable route exists.
The early density forecasts ran above the measurements. Investigators revised their models as our experimental campaign exposed differences from the historical specimens. Later forecasts anticipated the density increase at 850 °C, although most shared a physics tool and most followed RPI’s expectation. Across the full forecast record, carrying forward the previous density was often competitive with a revised model at repeated conditions.
The forecast record
Before any 850 °C specimen was reported, ten investigations froze density forecasts of 6.9 to 7.2 g/cm³. Most repeated the shared physics model’s output, and most were frozen after RPI shared its own expectation in a meeting. The first 850 °C specimen measured 7.01 g/cm³, inside all ten 90% intervals. Carrying the 800 °C results forward would have missed it by more than 1.3 g/cm³, and the shared physics model came out 0.25 g/cm³ high.
In subsequent work on our experimental campaign, Qwen and DeepSeek challenged Opus’s proposed degassing experiment. Qwen questioned whether density and microscopy could reveal the expected magnetic benefit; DeepSeek questioned the physical premise. With peer and operator input, Opus made its preference conditional on a plausible powder-state explanation and magnetic measurements.
Spark plasma sintering at RPI
Reconstruction · silentLimitations
SDL-2 v1.0 results come from the digital twin. Its worlds model isotropic magnets at room temperature, without alignment, grain-boundary diffusion or operating temperature, and their density level sits above the measured campaign specimens. Each model ran once per world in its own harness, so the panel compares complete agent systems on single attempts. The requirement is a calibration level rather than the program’s target.
Observations from our experimental campaign show model revision and method reuse. They do not establish physical transfer of the trained policy or fewer experiments to reach the material target.
Audit notes
A scoring fix to how final routes are read was applied after the results and raised Claude Sonnet 5.5 from five to six correct, justified decisions. The two Claude models shared one evaluation account. The 29 test worlds stay sealed, though these results have informed our later development work. The blinded expert audit that completes the verification ladder is not part of v1.0.
We tuned the classical policies on development worlds, then froze and preregistered them before the sealed runs. Each ran one deterministic attempt per world through the same harness without a language model and was scored under the same evaluator prior.
What’s next
The next capability is predicting which processing changes improve coercivity and energy product together. Magnetic measurements on matched as-sintered and annealed specimens will test the models and guide work on powder refinement, grain boundaries and alignment. The measured responses will inform the twin’s next exploration scenarios, where we aim to train agents to choose experiments that resolve the uncertainty controlling the material requirement.
If you work on materials for extreme environments, or on agents that learn from experiments, we would love to hear from you. Our open roles include an experimentalist to design the measurements that connect this work to real processes.
Related work
Optimal experimental design chooses experiments for a stated goal and can adapt to earlier results. SDL-2 evaluates agents that choose and revise their model. MatFlowBench checks computational materials workflows and replays archived measurements with executable verifiers. SciUniverse runs lab procedures on real instruments. FrontierXRD evaluates diffraction analysis with an expert-calibrated judge, and BixBench3 grades study-scale computational biology. SDL-2 adds whole investigations of a process under an experiment economy, a simulated outcome for every route an agent can propose and correctness scored separately from evidential support, and it sits inside a loop between a digital twin and an experimental campaign.
Citation
@article{barnes2026sdl2,
  author  = {Barnes, Jarrod},
  title   = {Teaching AI to Explore the Physical World},
  journal = {Dynamical Systems},
  year    = {2026},
  note    = {SDL-2 v1.0},
  url     = {https://dynamicalsystems.ai/blog/sdl-2}
}